Saved profiles
Keep repeatable configurations for the engine, model, placement, context and concurrency.
Helm RuntimeInside Helm Node
Configure, start and observe your local inference runtimes. Keep launch settings, readiness and client access in view.
Available within Helm Node.
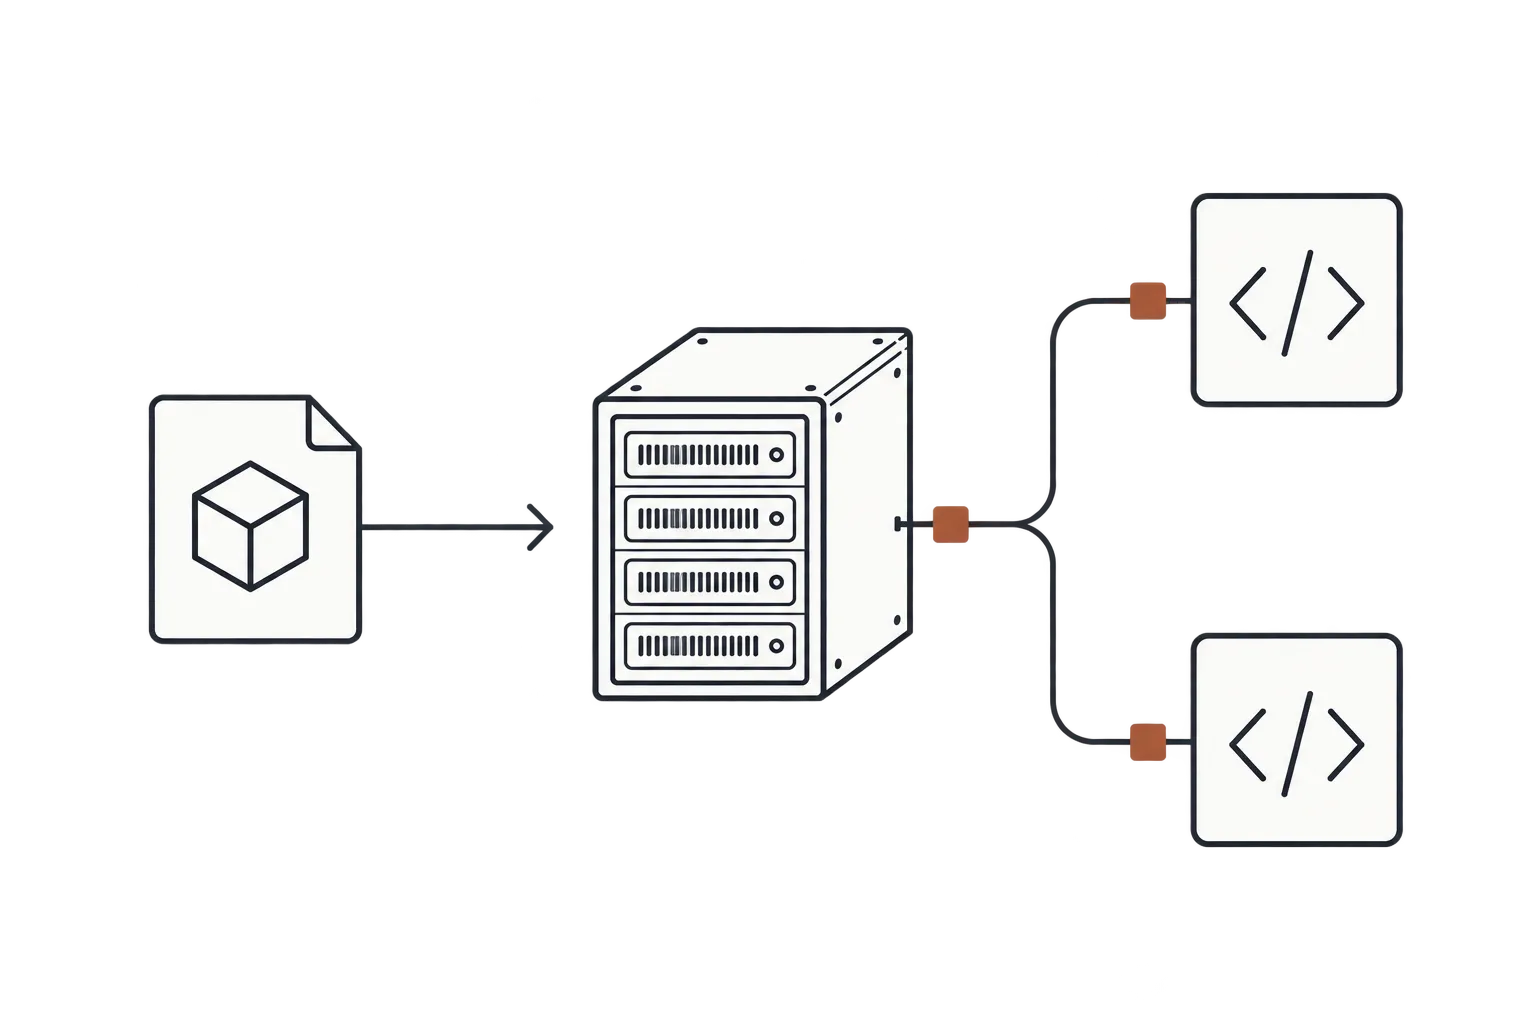
Keep repeatable configurations for the engine, model, placement, context and concurrency.
Bring profiles online, inspect readiness and let active requests finish before stopping.
Understand runtime state through health checks, bounded logs and endpoint details.
CAPABILITIES, CLEARLY DEFINED
vLLM support requires a configured controller and a supported model, recipe and GPU combination.